
Inside a Data Centre: What Actually Keeps a Website Online
Ask most people what keeps a website online and the answer is "the server". It is a reasonable answer and an incomplete one. The server is the last link in a chain of maybe seven, and it is almost never the link that fails.
Websites go down because a power feed dropped and nothing caught it, because a cooling loop failed on the hottest afternoon of the year, because a single upstream carrier had a bad hour, or because a maintenance window required someone to switch a machine off and there was no second path. Uptime is not a property of hardware. It is a property of a building, a network, and the people who run both.
Key Takeaways
- Availability is built in layers power, cooling, connectivity, hardware, storage, security and staffing. A weakness in any one of them caps the whole.
- N+1 redundancy means every critical component has a spare that can carry the load, so maintenance does not require downtime.
- Tier 3+ facilities are designed to be concurrently maintainable: any component can be serviced while the systems it supports stay running.
- Network resilience comes from multiple independent carriers and direct exchange peering, not from raw bandwidth.
- Software-defined storage with replication protects against drive and node failure in ways RAID on a single machine cannot.
Layer one: power that does not stop
Power is where redundancy is most visible and most expensive. A serious data centre does not have a power supply it has several, arranged so that no single failure reaches the racks.
In the Equinix facility our infrastructure occupies, that means four independent power feeds and four dedicated transformers, so the loss of one utility path is absorbed rather than propagated. Behind that sit uninterruptible power supplies capable of carrying the full load for twenty minutes, and five synchronised diesel generators with unlimited runtime as long as they are refuelled.
The twenty-minute figure sounds short until you understand its role. UPS capacity is not there to ride out an outage; it is there to bridge the gap between the utility failing and the generators reaching stable load a matter of seconds under normal circumstances. The remaining minutes are margin for the case where a generator does not start on the first attempt.
The important design principle underneath all of it is N+1: every separate component has at least one spare capable of taking the load. That is what makes a facility concurrently maintainable you can service a UPS, a transformer or a cooling unit without switching off anything that depends on it.
Layer two: cooling, the quiet cause of most thermal incidents
Servers convert electricity into heat with high efficiency. A well-populated cabinet can dissipate as much heat as a small domestic heating system running continuously, and silicon protects itself by throttling long before it fails which is why thermal problems usually present as inexplicable slowness rather than as an outage.
Modern facilities manage this by controlling airflow rather than simply chilling the room. A Cold Aisle Containment System encloses the cold aisle so that chilled air is delivered to the front of the equipment and cannot mix with the hot exhaust behind it. The result is a stable, predictable intake temperature at every rack position instead of hot spots at the top of the cabinet.
Cooling capacity is expressed per cabinet up to twelve kilowatts in our racks, with in-row water cooling available for higher-density deployments and the internal systems carry the same N+1 redundancy as the power chain. A failed cooling unit reduces headroom; it does not raise the room temperature.
Layer three: connectivity, where most real outages happen
If a site is unreachable, the cause is more often the network than the machine. This is also the layer where the difference between providers is largest and least visible from the outside.
Bandwidth is the number everyone quotes and the least interesting one. What actually determines whether traffic keeps flowing is the number of independent paths and how quickly routing converges when one of them fails. A single carrier with ten gigabits is more fragile than three carriers with one gigabit each, because carrier-level incidents are common and are not solved by capacity.
Delta Hosting runs on three independent internet providers with over 300 Gbps of capacity and four or more direct, reserved connections to Tier 1 operators, plus direct peering at the major exchanges BIX and NetIX domestically, DE-CIX internationally. Domestic peering reaches effectively all Bulgarian networks directly, which removes an entire class of failure and shortens the path for local visitors at the same time.
Sitting in front of that is DDoS mitigation at layers 3 and 4, backed by twelve terabits per second of network edge capacity across more than twenty points of presence. Volumetric attacks are absorbed upstream, before they reach the port your server is connected to which is the only place absorbing them is possible.
Layer four: hardware and storage that expect failure
Individual components fail on a predictable schedule. Drives fail. Power supplies fail. Memory develops errors. Designing around this is more effective than trying to prevent it.
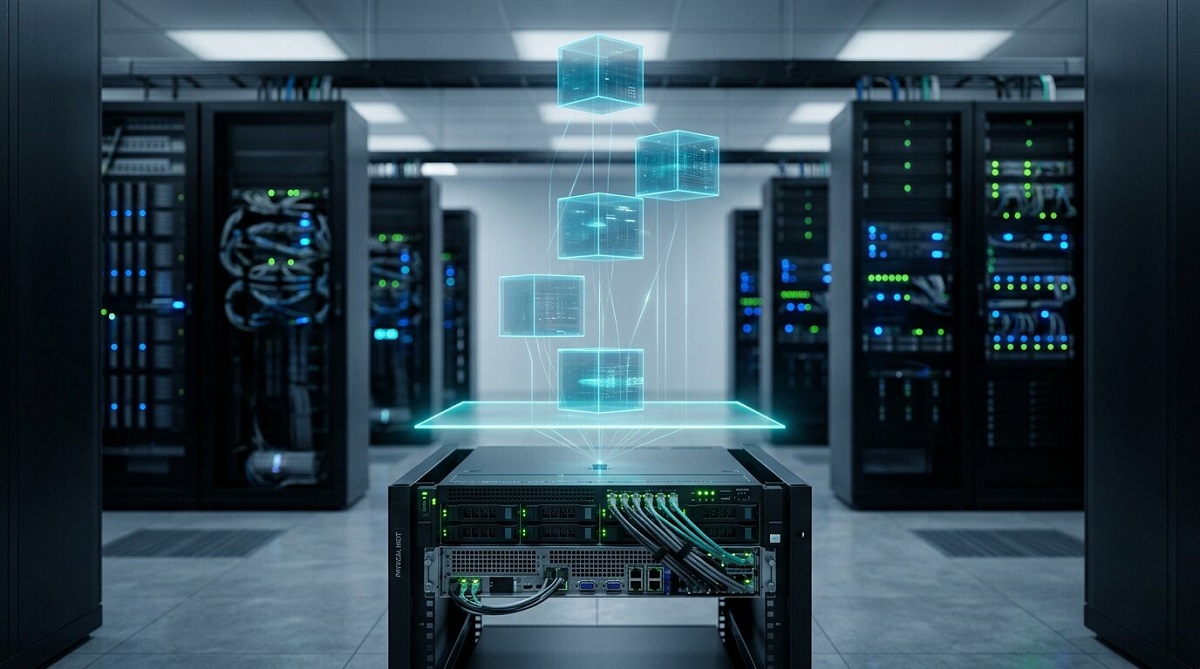
At the platform level, our cloud runs on OpenStack with AMD EPYC processors and an all-NVMe storage layer built on Ceph, holding three replicas of every piece of data across separate nodes. A drive failure is a background event; a node failure is a background event. Neither requires a restore, because two other copies remain live.
This is a meaningfully different guarantee from RAID inside a single chassis. RAID protects against drive failure within one machine. It does nothing about the machine itself a failed backplane, controller or motherboard takes the array with it. Distributed replication removes the machine as a single point of failure, which is precisely the failure mode single-server setups are exposed to.
Snapshots and backups sit on top as a separate concern. Replication protects against hardware failure; it faithfully replicates a mistaken deletion or a compromised application three times over. The two mechanisms answer different questions and neither substitutes for the other.
Layer five: physical security and fire
The least discussed layer, and the one with the largest consequences when it fails.
Access to the facility is controlled and logged, with video surveillance throughout and armed security on site. Fire detection runs on multiple zones with dual-trigger alarms thermal and smoke sensors that must both agree before suppression activates, which prevents an expensive false positive from causing the incident it was installed to avoid.
The facility also runs entirely on green energy and holds ISO 9001, ISO/IEC 27001, ISO 50001 and ISO 14001 certification. Certification is not a performance figure; it is evidence that the processes behind these systems are audited by someone other than the people who operate them.
Layer six: the people
Every mechanism described so far is designed to buy time for a human being to act. Redundancy converts an outage into a degraded state, and a degraded state into a ticket. If nobody reads the ticket, the redundancy has only delayed the outage.
This is why monitoring and staffing belong in any honest description of availability. Someone has to notice that one of two power paths is now carrying the whole load, that a cooling unit has dropped out, or that a replica has not rejoined the cluster and to fix it before the second failure arrives. Delta.BG operates its infrastructure with 24/7 monitoring and administration for exactly this reason, and it is the layer that most often distinguishes a facility that looks resilient on paper from one that behaves resiliently in practice.
What this means for your website
Two practical conclusions follow.
First, uptime figures should be read as descriptions of design, not as promises. A 99.99% availability target on our cloud platform and 99.9% on dedicated hardware reflect the redundancy actually present at each layer not marketing rounding.
Second, the layers your provider handles are only part of the picture. A single unreplicated database on a single instance is a single point of failure no data centre can compensate for. The building keeps the machine running; the architecture keeps the service running. Both are needed.
Conclusion
Nothing about staying online is a single decision. It is four power feeds and five generators, contained cold aisles and N+1 cooling, three carriers and direct peering, three copies of every block, controlled access and dual-trigger fire detection, and someone awake to read the alert.
Most of the time, none of it is visible. That is the entire point the measure of a well-run facility is that the people depending on it never learn how much happened on their behalf.
Want infrastructure with these layers already in place? Delta.BG runs Cloud VPS, Dedicated Servers and Colocation from an Equinix Tier 3+ data centre in Sofia, with N+1 power and cooling, 300+ Gbps of multi-carrier connectivity, DDoS protection and 24/7 monitoring. Reach our team on +359 2 4 288 288 or at [email protected].